A PDF reader plugin for narration
A proposed PDF-to-narration pipeline for books, documents, and PRDs that need a useful listening version.
The job
Many useful documents are difficult to consume in the format in which they arrive.
A book may not have an audio edition. A PRD may be long enough that I want to review it while walking. A scanned document may contain valuable material but no usable text layer.
The PDF Reader plugin should turn those files into narration-ready material. The result can then move into ElevenLabs or another narration tool.
The goal is not to upload a PDF and hope that a voice model understands it. The goal is to produce a clean, reviewable script before narration begins.
The pipeline
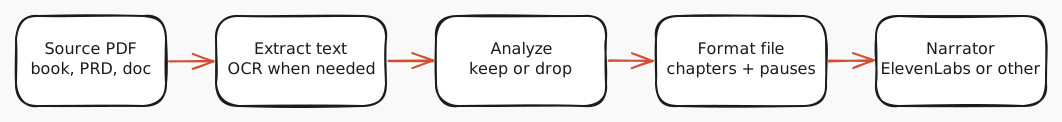
The pipeline has four decisions between the source file and the narrator:
1. Extract the existing text, or use OCR when a page is scanned. 2. Recover the reading order and document structure. 3. Decide what the spoken version should keep, drop, or rewrite. 4. Format a portable narration file and prepare the provider handoff.
Each stage should leave an artifact that I can inspect. A bad extraction must not become an expensive audio file before anyone notices.
Text first, OCR when needed
The plugin should inspect each page before choosing an extraction method.
If the PDF has a reliable text layer, direct extraction is faster and usually more accurate. If a page is an image, the plugin should use optical character recognition, or OCR. Mixed PDFs may need both methods in the same document.
OCR confidence matters. Uncertain words, broken paragraphs, and ambiguous reading order should be flagged for review instead of silently guessed.
The source page number should remain attached as metadata. I may remove page numbers from the spoken script, but I still need a path back to the original passage.
Decide what belongs in the spoken version
A PDF contains more than its main text. It can include repeated headers, footers, page numbers, navigation, citations, tables, image captions, legal notices, and margin notes.
The plugin needs a keep-or-drop pass that understands the purpose of the output.
For a book, it may keep chapter titles and meaningful footnotes while dropping repeated furniture. For a PRD, it should keep requirements, decisions, risks, and open questions. It may move dense tables into a separate review section instead of reading every cell aloud.
This pass must produce a decision log. Dropped material remains in the original PDF and appears in the log with its source location. The plugin should never make irreversible edits to the source.
The default should preserve meaning, not summarize it. Summaries and rewrites are separate choices because they can change the author's intent.
Format for narration
The clean output should not depend on one voice provider.
A neutral narration file can contain:
- chapter and section boundaries
- paragraph breaks and pause markers
- pronunciation notes for names and technical terms
- source references for review
- warnings for unresolved OCR or layout problems
An adapter can then turn that file into the format required by ElevenLabs or another narrator. Provider settings, voices, and credentials stay outside the document-processing stage.
This separation makes the useful artifact portable. If the narrator changes, the expensive extraction and editing work does not need to happen again.
The review checkpoint
Before export, the plugin should show a short report:
- pages processed through text extraction and OCR
- sections kept, dropped, or moved
- low-confidence passages
- estimated chapter boundaries
- narration files ready for export
I should be able to preview the script, correct a name, restore a dropped section, and then approve the handoff.
That checkpoint is the product. Without it, the workflow is only a chain of automated guesses.
Why this is useful
The immediate use case is personal listening: books without an available audio edition, documents, research material, and PRDs that are easier to review away from a screen.
The same pipeline can support accessibility and internal knowledge workflows. A team could prepare a long strategy document for listening without manually cleaning every page.
The tool should only process material that the user has the right to access and convert. It should create a private working copy, not a new distribution channel.
The useful version of this plugin is small. It accepts a PDF, explains what it changed, and returns a narration-ready file that I trust enough to hear.
Related notes
Creator Copilot as an internal tool
Why Creator Copilot starts as an internal system for turning founder notes into consistent public content.
Manual RAG for a personal site
An imported note about building a low-cost local retrieval layer for a personal website chat experience.